BioPharmaTrend
Latest Insights
Companies
  • Companies Directory
  • Case Studies
Newsletter
About
  • At a Glance
  • Our Team
  • Advisory Board
  • Citations and Press Coverage
  • Partner Events Calendar
  • Advertise with Us
 
 Subscribe 
Sign in
  • AI in Bio
  • Tech Giants
  • Next-Gen Tools
  • Business Intelligence

  Business Intellilgence

Protein Language Models: Builders & Pharma Deals

by BiopharmaTrend   •   Nov. 14, 2025

Disclaimer: All opinions expressed by Contributors are their own and do not represent those of their employers, or BiopharmaTrend.com.
Contributors are fully responsible for assuring they own any required copyright for any content they submit to BiopharmaTrend.com. This website and its owners shall not be liable for neither information and content submitted for publication by Contributors, nor its accuracy.

Share:   Share in LinkedIn  Share in Bluesky  Share in Reddit  Share in Hacker News  Share in X  Share in Facebook

Chan Zuckerberg Initiative, the group behind the recent virtual cell efforts, has “acqui-hired” EvolutionaryScale’s ~50-person team, folding it into the expanding Biohub network. The move comes as CZI pivots to center nearly all its resources on AI-driven biology. EvolutionaryScale’s chief scientist, Alex Rives, will now serve as Biohub’s new head of science, succeeding Steven Quake.

EvolutionaryScale emerged in 2023 after Rives, along with Tom Sercu and Sal Candido, left Meta’s AI protein group (FAIR) during the company’s “year of efficiency” (there are, again, plans to cut 600 AI jobs after a $14.3 billion Scale AI investment and hiring spree this summer). Backed by the likes of Amazon and Nvidia, the team raised $142 million to develop large-scale generative models for protein design and became known for the ESM family of protein language models (PLMs) trained directly on amino-acid sequences.

Its flagships, ESM3 and ESM Cambrian, extended this work to fully generative modeling of protein structure and function. ESM3, trained on 2.7 billion proteins, has already been used to design molecules like the novel green fluorescent protein variant, esmGFP, said to represent roughly 500 million years of natural evolution.

CZI’s Biohub folds this hire into its broader “virtual biology” plan, setting out four scientific challenges: building an AI-based model of the cell, advancing imaging, instrumenting inflammation, and using AI to reprogram the immune system, with the Virtual Immune System as one of the flagship projects. The ES team is brought in “to help advance this initiative.” In the VIS roadmap, the molecular-interactions axis explicitly calls for protein language models that “can learn the universal grammar of immune recognition and enable the rational design of novel receptors.”

With that, let’s step back and look closer at what protein language models are, what kinds of applications companies are building them for, and where pharma is already involved.


In this article: Proteins & Language — Players & Pharma Collaborations — Sequence-Structure Gap — Challenges & Prospects


Proteins & Language

There’s a long-running analogy between proteins and natural language. Amino-acid sequences are strings over a 20-letter alphabet; they fold into secondary, tertiary, and quaternary structures in roughly the same way letters form words, sentences, and longer texts that carry meaning (in this case, function). Local context matters, but so do long-distance effects: amino acids that are far apart along the sequence can contact each other in 3D, much like dependencies between distant words or clauses in a document. Because of these parallels, researchers have been importing Natural Language Processing (NLP) tools into protein work for decades.

But the analogy has its limits. Proteins don’t have clean “word” boundaries, the underlying “grammar” is poorly understood, and evolution introduces all kinds of irregularities. At the same time, sequence databases have exploded in size, while structures and functional labels lag behind, creating sequence–structure gap. That mix of massive sequence datasets and limited structural or functional labels looks a lot like the setting where self-supervised language models first proved useful in NLP. So it is natural to try similar objectives on protein sequences, even though this isn’t a direct port of NLP into biology, rather, it’s more a case of borrowing inductive biases and training strategies to explore the protein sequence–function landscape in new ways.

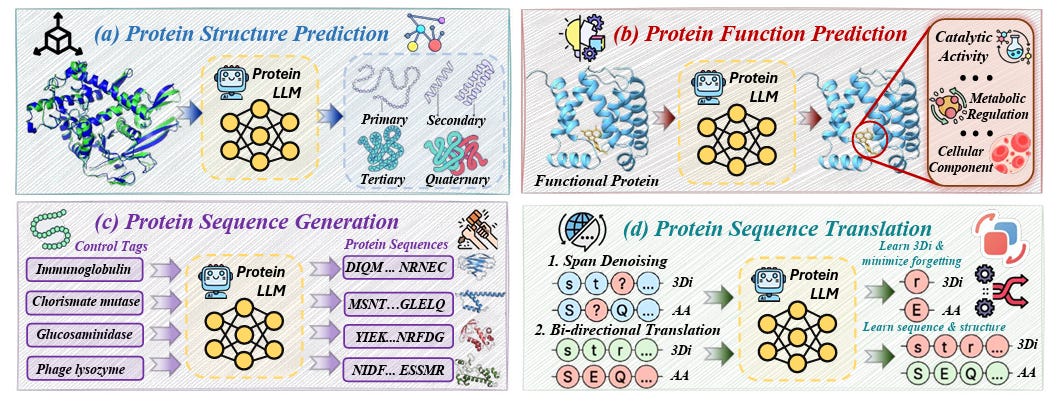
Transformers are the latest step in that cross-over, where instead of hand-crafted features or shallow models, large PLMs are trained directly on raw sequences at scale. Some are set up to fill in masked amino acids and learn embeddings that have been used for tasks like contact prediction or estimating the effect of mutations. Others are built as generative models that can propose entirely new sequences and, in some cases, can be steered with broad tags for things like function or cellular compartment. In parallel, researchers are starting to look at the attention patterns inside these models as one possible way to probe how they relate distant positions in a sequence and what that might say about folding and design.


Overview of tasks in PLM. From: “Protein Large Language Models: A Comprehensive Survey” License: CC BY 4.0

Roughly, we can think of three generations of protein modelling:

  1. First-generation methods hand-crafted features from amino-acid composition and position, with ad-hoc corrections for dataset biases, and powered early secondary-structure and signal-peptide predictors.
  2. Second-generation methods coupled machine learning to evolutionary information from multiple-sequence alignments, starting in secondary-structure work and later becoming central to 3D prediction in models like AlphaFold2.
  3. Third-generation methods train large PLMs directly on raw sequences with auto-encoding and autoregressive objectives, treating amino acids like words and learning reusable representations for sequence/structure prediction, function annotation, and protein design.

Players & Pharma Collaborations

There are multiple protein design companies developing general or specific PLMs. Many of them co-develop models with pharma enterprises or use tech cloud facilities to maintain and upscale the existing protein systems.

To read the rest of this article, upgrade to a BiopharmaTrend Pro subscription.

Gain full access to all of our deep dives and content archives.
 Upgrade to Pro 

Already a member? Sign in here.
Share:   Share in LinkedIn  Share in Bluesky  Share in Reddit  Share in Hacker News  Share in X  Share in Facebook

BiopharmaTrend.com

Where Tech Meets Bio
mail  Newsletter
in  LinkedIn
x  X
rss  RSS Feed

About


  • What we do
  • Press & Citations
  • Terms of Use
  • Privacy Policy
  • Cookies Policy
  • Disclaimer

Topics


  • News
  • AI in Bio
  • Tech Giants
  • Next-Gen Tools

Explore


  • Premium Insights
  • Business Intelligence
  • Companies
  • Events
  • Authors

Partner


  • Sponsorship
  • Editorial Calendar

© WTMB Research & Media, S.L. (WTMB Group)   2026
We use cookies to personalise content and to analyse our traffic. You consent to our cookies if you continue to use our website. Read more details in our cookies policy.