BioPharmaTrend
Latest Insights
Companies
  • Companies Directory
  • Case Studies
Newsletter
About
  • At a Glance
  • Our Team
  • Advisory Board
  • Citations and Press Coverage
  • Partner Events Calendar
  • Advertise with Us
 
 Subscribe 
Sign in
  • AI in Bio
  • Tech Giants
  • Next-Gen Tools
  • Business Intelligence

  Business Intellilgence

Generative Diffusion in Molecular Design

by BiopharmaTrend   •   Nov. 27, 2025

Disclaimer: All opinions expressed by Contributors are their own and do not represent those of their employers, or BiopharmaTrend.com.
Contributors are fully responsible for assuring they own any required copyright for any content they submit to BiopharmaTrend.com. This website and its owners shall not be liable for neither information and content submitted for publication by Contributors, nor its accuracy.

Share:   Share in LinkedIn  Share in Bluesky  Share in Reddit  Share in Hacker News  Share in X  Share in Facebook

A quick field guide to diffusion-based generators in molecular design—how they work, where they complement transformers, and who is deploying them today.

Last week, Californian drug discovery startup Terray Therapeutics introduced an experimentation-based machine intelligence platform called EMMI. The platform unites the company’s proprietary ultra-dense microarray technology with an AI stack built around its COATI foundation model, which maps chemical representations to respective molecular properties for better scientific understanding. EMMI is designed to guide R&D reasoning and propose molecular candidates with the later refinement and validation. Terray couples a 13-billion-measurement binding dataset with COATI-based diffusion and RL generators, and an uncertainty-aware selection layer, into a closed-loop system that decides not only what to propose but also which molecules are worth the cost of actually making and testing. In 2024, the company released its first latent diffusion-based molecular generator.

Terray’s work in diffusion methods prompted a broader reflection on generative AI in biology. Today, most conversations and publications center on Transformer-based systems, especially large language models (LLMs) and other foundation models (FMs). LLMs make up a major subset of FMs, but whereas language models are trained primarily on textual data like natural language, code, or biological sequences, foundation models extend the paradigm to additional modalities, including images, audio, video, and even multimodal combinations.

Recent meta-reviews in biomedical NLP collectively catalog nearly 300 LLM instances across hundreds of studies. Foundation models are also proliferating, with over 200 tools developed since 2022 in drug discovery alone. In contrast, the literature on diffusion models for biological and chemical applications remains comparatively modest. So far, there have been only a handful of reviews capturing the diffusion generators. Yet despite lower popularity, diffusion architectures are carving out a meaningful and distinctive role in biotech research and industry.

Before diving deeper into their role in biomedicine, let’s briefly review how diffusion models work in general.


In this article: Diffusion Models 101 — With or against Transformers? — Diffusion Models in Biomedicine — Dispersed Players — Diffusion Online Stations — An Afternote

Diffusion Models 101

Diffusion models are a type of generative AI architecture best known in computer vision as the backbone of image synthesis tools like Stable Diffusion (Stability AI), DALL-E 2/3(Open AI), Midjourney or Imagen (Google).

Diffusion models grew out of earlier image generators like GANs, which could produce impressive pictures but were often hard to train and tended to reuse the same patterns. Researchers explored a different, simpler route: instead of forcing a network to create an image in one shot, let it start from pure noise and learn how to clean that noise up step by step.

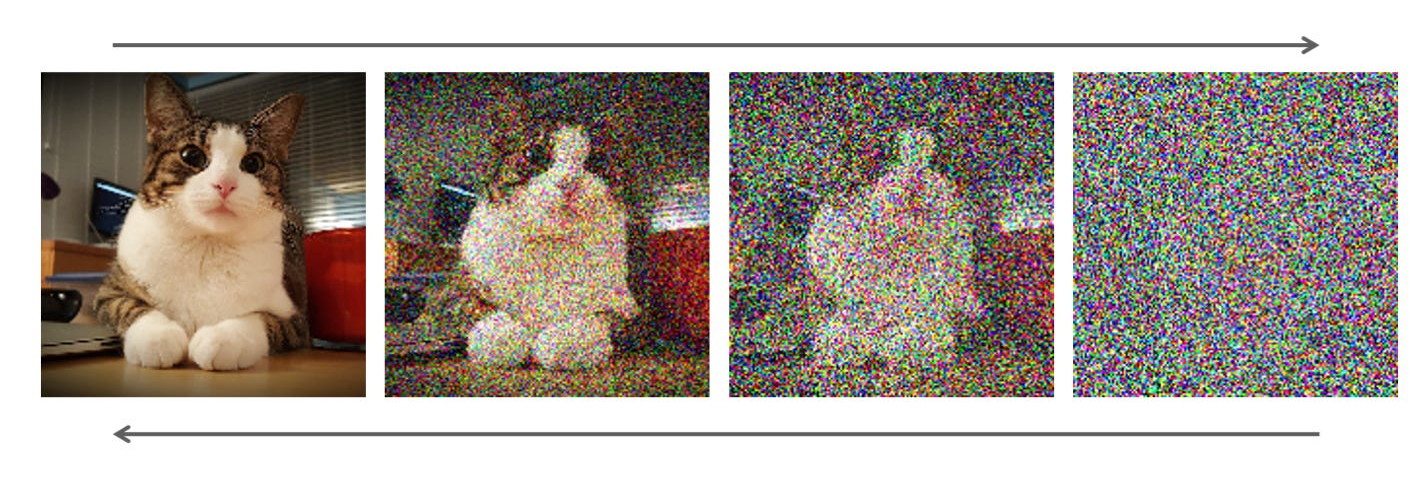
The core intuition comes from physics: one could imagine an ink drop dispersing in water, where the original shape gradually dissolves into a uniform blur. In the same way, a diffusion model takes real images during training and slowly corrupts them with noise until they look like TV static, then learns how to reverse that process one small step at a time. After training, it can start from random noise and repeatedly “denoise” it into an image that statistically looks like it could have come from the training set.

This idea was first written down in 2015 by Sohl-Dickstein and colleagues in work on “nonequilibrium thermodynamics,” and in 2020 Ho et al. turned it into the denoising diffusion probabilistic models (DDPMs) that underpin today’s systems; modern text-to-image tools such as Stable Diffusion, DALL-E, and Imagen pair this diffusion backbone with a text encoder that steers the denoising toward what the written prompt describes.

The diffusion model training and deployment is based on two core processes:

  • Forward diffusion process - clean training images get diffused step-by-step by adding Gaussian (following normal distribution) signal noise until the data turns into a pure noise
  • Reverse diffusion process - the neural network learns to invert these small noising steps, effectively becoming a powerful denoiser
  • Once trained, the model can perform image generation by starting from random noise and iteratively applying its learned denoising steps to obtain a coherent image


From: Improving Diffusion Models as an Alternative To GANs, Part 1. Authors: Arash Vahdat and Karsten Kreis.

This incremental approach gives diffusion models several advantages. Rather than forcing a network to create an entire image in one leap, they break the task into many small, manageable refinements. The result is stable training and sharp, customizable output. Modern versions often run the diffusion process in a compressed latent space—an abstract representation where images are encoded as dense numerical features rather than full-resolution pixels. Working in this space makes generation faster and efficient, while still preserving the essential structure needed to reconstruct high-quality images. These models can also be guided by prompts, sketches, or other inputs to steer generation toward specific concepts.

While diffusion models are best known for powering text-to-image tools, their usefulness isn’t limited to visual art. Just as DALL-E generates images from text, what if, instead of pixels, the same architecture is applied to atom coordinates to generate amino acid backbones?


To read the rest of this article, upgrade to a BiopharmaTrend Pro subscription.

Gain full access to all of our deep dives and content archives.
 Upgrade to Pro 

Already a member? Sign in here.
Share:   Share in LinkedIn  Share in Bluesky  Share in Reddit  Share in Hacker News  Share in X  Share in Facebook

BiopharmaTrend.com

Where Tech Meets Bio
mail  Newsletter
in  LinkedIn
x  X
rss  RSS Feed

About


  • What we do
  • Press & Citations
  • Terms of Use
  • Privacy Policy
  • Cookies Policy
  • Disclaimer

Topics


  • News
  • AI in Bio
  • Tech Giants
  • Next-Gen Tools

Explore


  • Premium Insights
  • Business Intelligence
  • Companies
  • Events
  • Authors

Partner


  • Sponsorship
  • Editorial Calendar

© WTMB Research & Media, S.L. (WTMB Group)   2026
We use cookies to personalise content and to analyse our traffic. You consent to our cookies if you continue to use our website. Read more details in our cookies policy.