Building the Virtual Cell: AI Foundation Models and Billion-Cell Datasets
From early 2000s and a 2012 milestone to a decade-long quiet—virtual cell modeling is resurging with transformers, perturbation atlases, and lab-in-the-loop systems
While the term “virtual cell” initially goes back to the early 2000s from the Trends in Biotechnology article “Whole-cell simulation: a grand challenge of the 21st century” by M. Tomita, mainstream attention to full-cell simulation began with the 2012 Stanford Mycoplasma model. After a long lull, there’s now a resurgence of interest in modeling whole cells—this time driven by advances in machine learning, multimodal omics, and large-scale data integration.
Cells are central to understanding health, aging, and disease. They are also the primary testbed for applications in drug development and synthetic biology. However, cell-based experiments are costly and highly variable, raising concerns about reproducibility in biomedical research.
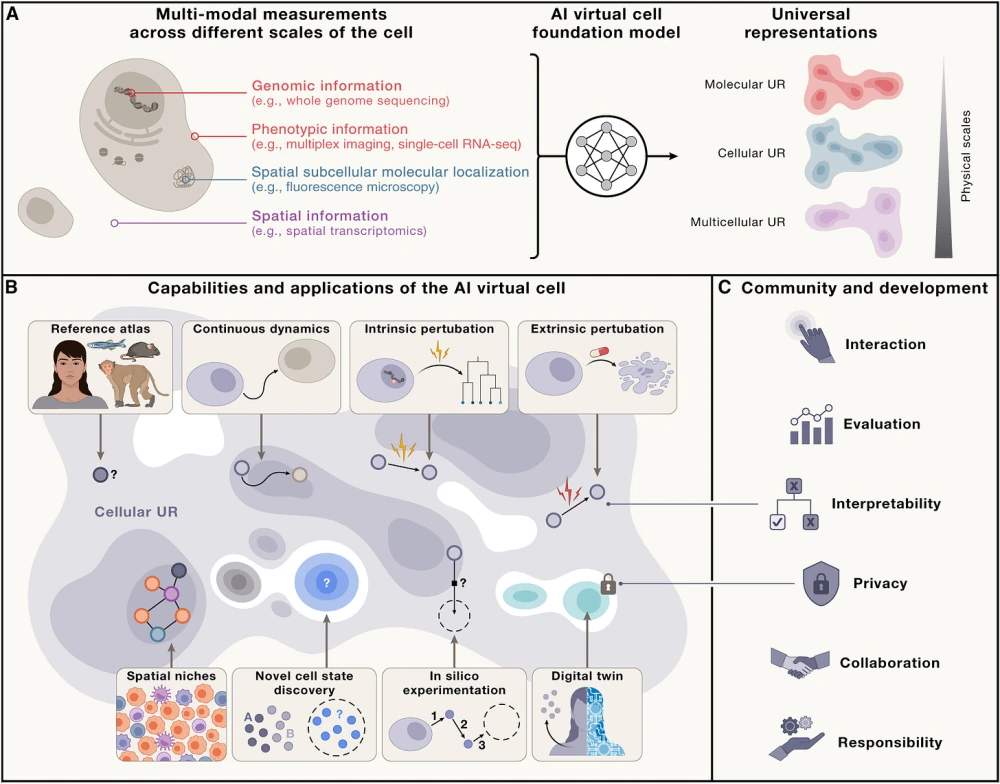
The ambition behind virtual cells is to build in silico models that can simulate, predict, and manipulate cellular behavior, reducing reliance on physical experimentation. A functioning virtual cell could accelerate hypothesis testing, guide therapeutic development, identify causal mechanisms of disease, and enable scalable experimentation—particularly in cases where direct observation is impractical or impossible.
As these models evolve, one long-term practical goal is to develop patient-specific “virtual twins”: dynamic, data-integrated simulations of individual cellular systems that can forecast treatment responses and inform personalized interventions.
In this article: The outline of a modern Virtual Cell — Pre-AIVC era — The AIVC — Big Tech Enters — No Data-No Party — Reality Check — The Holy Grail of Digital Biology
To read the rest of this article, upgrade to a BiopharmaTrend Pro subscription.
Gain full access to all of our deep dives and content archives.